
Evaluating LLM Features With Metrics That Matter in Ops
Skip vanity demos. Instrument task success, escalation rate, and cost per resolved intent.
Define the job to be done
Watch escalation and edits
If humans rewrite every answer, the model is not helping. Track edit distance, escalation reasons, and repeat contacts after AI handling.
- Task success rate by intent / workflow
- Human edit rate and escalation reason taxonomy
- Latency p50 / p95 and timeout rate
- Cost per successful task (not per token vanity)
Price the tokens
Cost per successful task keeps architecture honest. RAG, caching, and smaller models often beat a bigger context dump once you measure end-to-end.
Alert on cost anomalies the same way you alert on error rates. A silent prompt change can multiply spend overnight.
Offline eval plus online truth
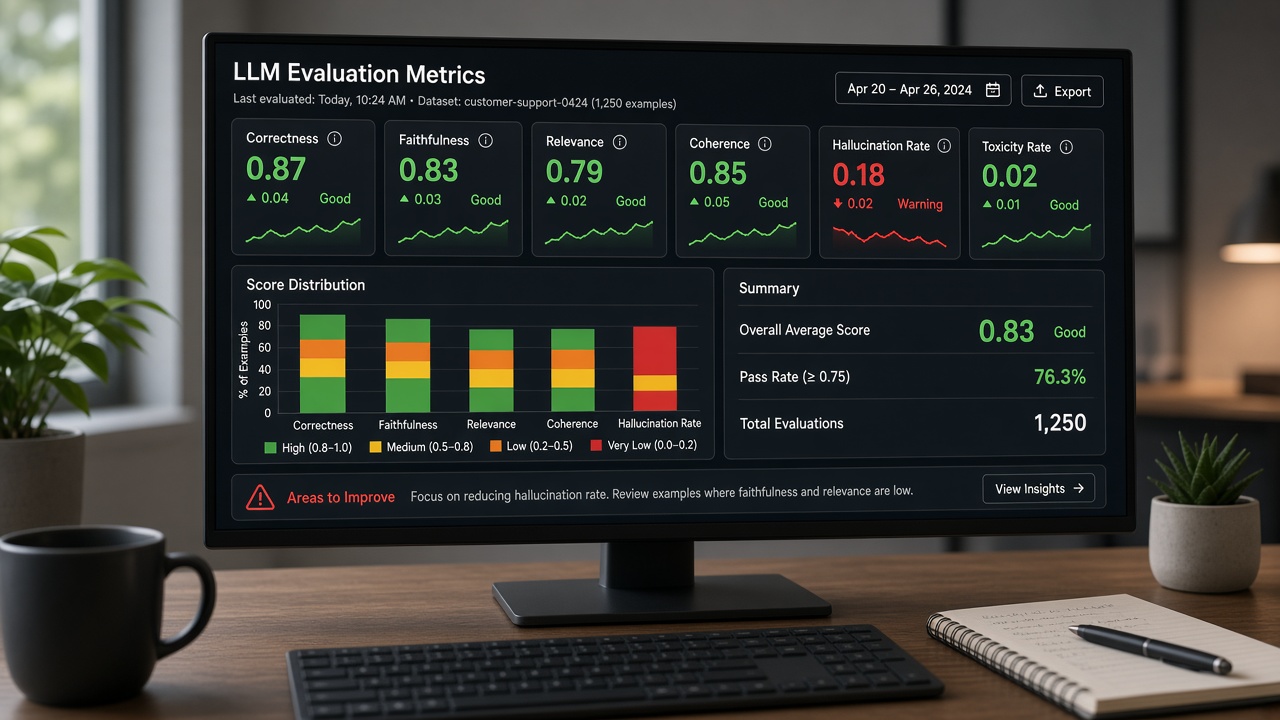
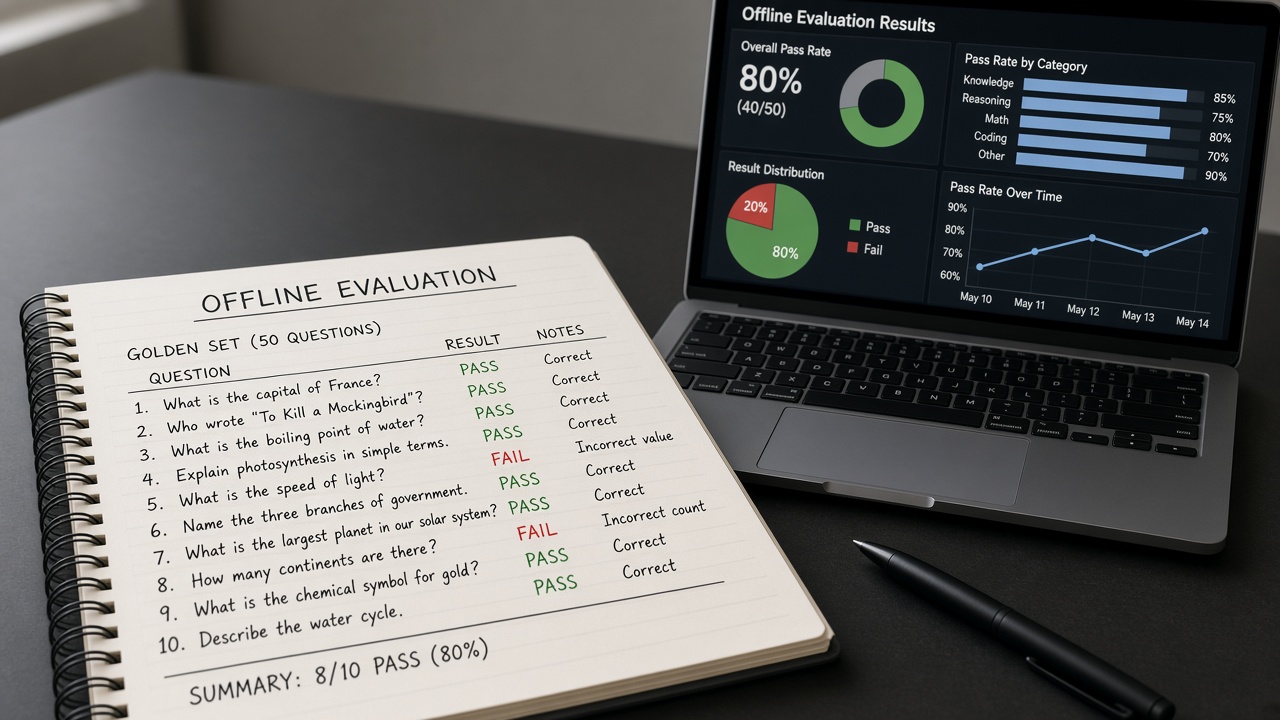
Golden sets catch regressions before deploy. Online metrics catch distribution shift after. You need both. Neither alone is enough for LLM features that touch customers.
Publish a simple weekly scorecard to stakeholders. Transparency buys patience when you are iterating; silence invites cancelation.
If you cannot show task success, escalation, and cost on one page, you are not ready to call the feature production.