
Why RAG Beats Blind Long Context for Enterprise Knowledge
Stuffing PDFs into a long window feels easy until citations break and costs explode. Retrieval keeps answers grounded.
Long-context models are impressive. They are not a substitute for a knowledge architecture. Enterprises that paste entire drives into a prompt discover three problems fast: missing provenance, runaway cost, and answers that sound confident while citing nothing usable.
Context is not a knowledge strategy
Long context helps for a single large document or a short working set. Enterprise knowledge is many sources, permissions, and weekly updates. Blind stuffing hides provenance and makes every query pay for tokens you did not need.
When a policy changes, can you prove which version the model saw? With raw dumps, usually not. With retrieval, you can re-index, version chunks, and retire stale passages deliberately.
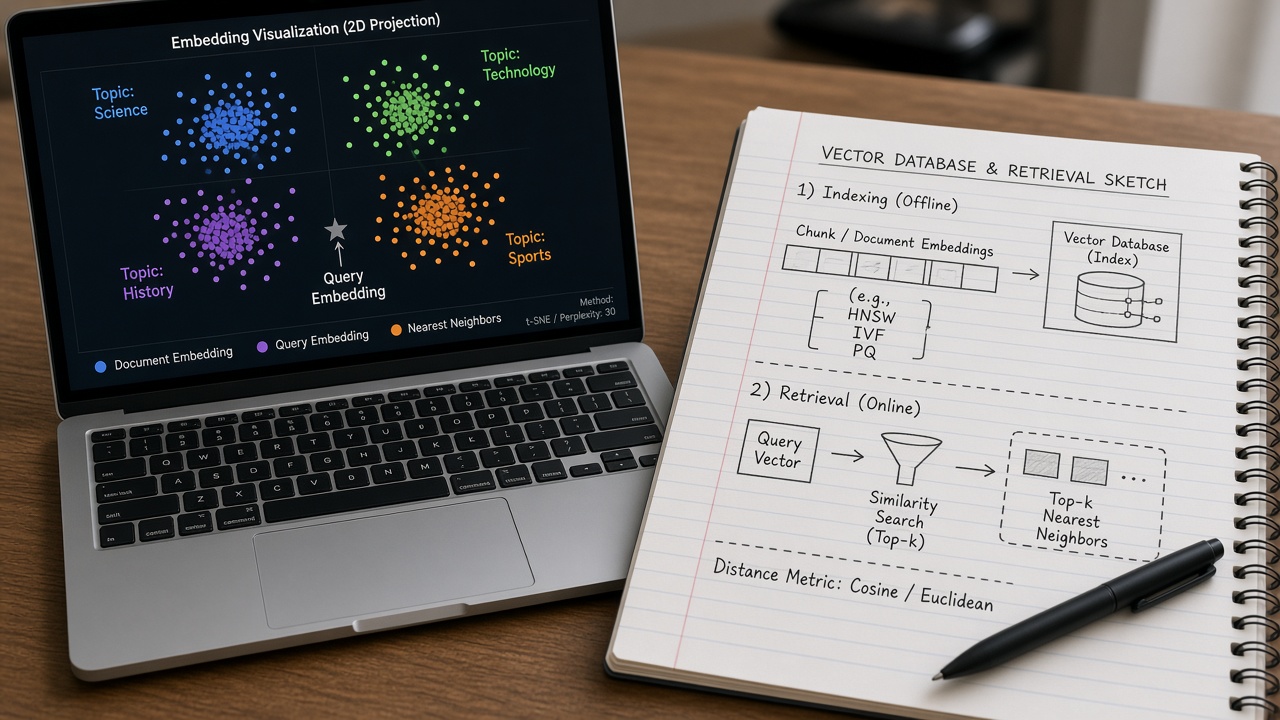
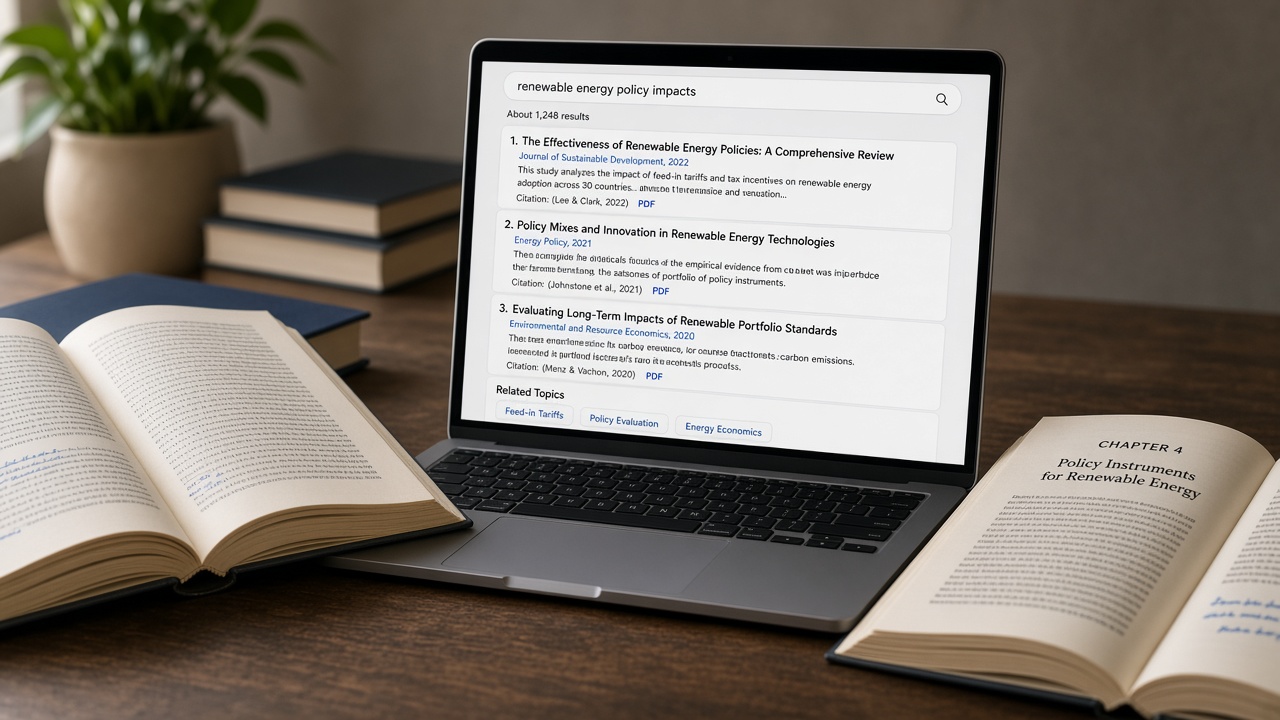
Retrieval forces citations
Citation UI is not a nice-to-have. It is the difference between a knowledge assistant and a liability generator.
- Chunk with structure: headings, tables, and section IDs preserved
- Hybrid search (keyword + vector) for exact terms and semantic matches
- Permission-aware retrieval so users only see what they can already access
Hybrid still wins
Evaluation that catches silent failure
Re-run the set on every corpus or prompt change. Knowledge systems drift; your tests should notice before customers do.