Next Gen System builds production chatbots, Voice AI, bot & process automation, agentic systems, OpenAI integrations, and data services—wired to your workflows.
Next Gen System builds production chatbots, Voice AI, bot & process automation, agentic systems, OpenAI integrations, and data services—wired to your workflows.
Service
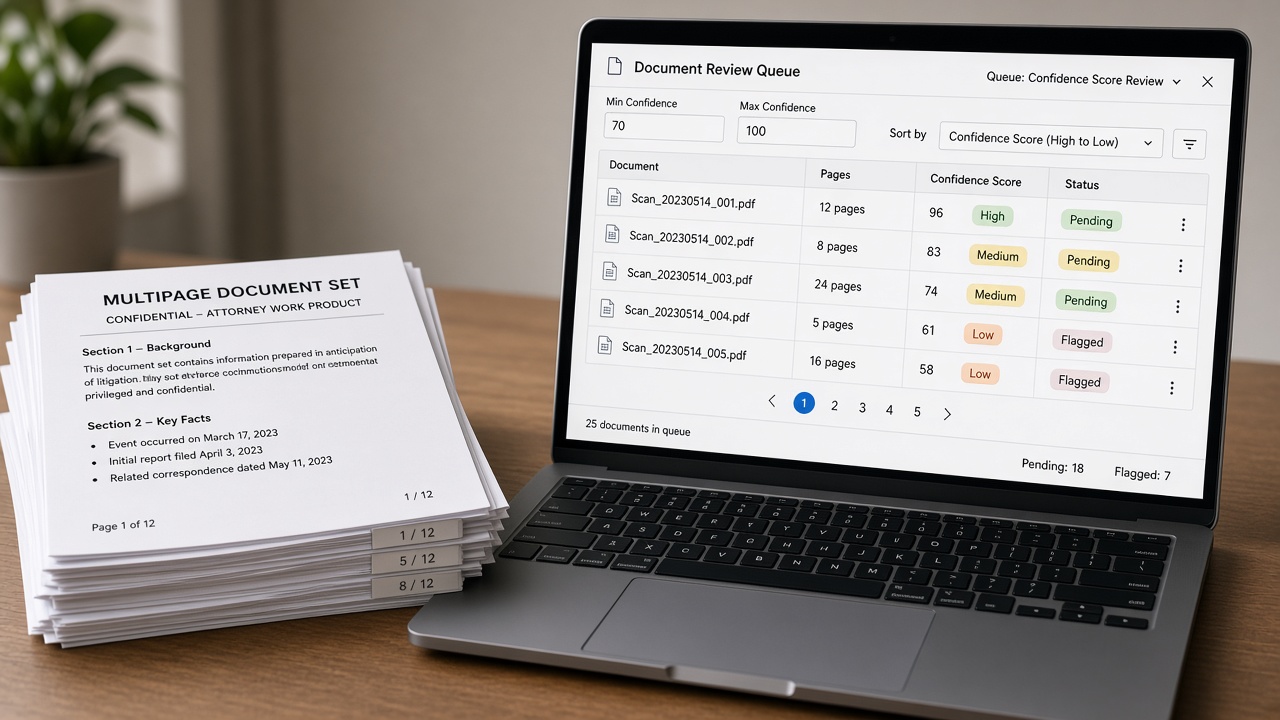
Extraction with confidence scores and human review—not blind automation.
Built for Ops teams buried in PDFs, emails, and forms.
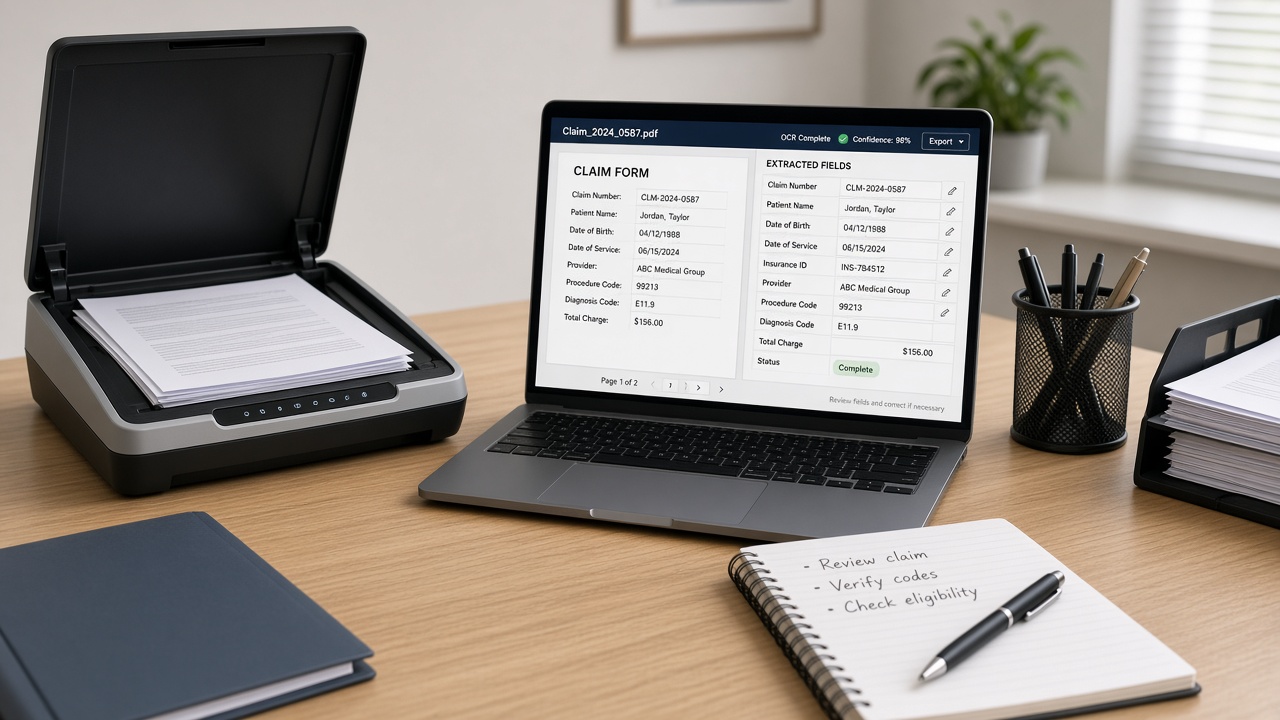
We extract structured fields from PDFs, emails, images, and forms using OCR, layout models, and LLMs where they help—paired with confidence scores and human review queues for high-stakes data.
Document and unstructured data extraction with accuracy controls and human review.
Project types
Concrete builds we ship under this service—not a generic AI wishlist.
Industries
How this service shows up in each sector—specific jobs, not a generic industry list.
IFUs, registrations, and lab PDFs become fields in the system of record, with confidence scores and a review queue for the misses.
View industry HealthcareReports and requisitions turn into structured results your LIS can load—humans only see low-confidence rows.
View industry HealthcareStudy packs, vendor invoices, and SOP scans extract into tables with an audit of what the model (or OCR) changed.
View industry HealthcareClaims, EOBs, and attachments become usable fields so intake is not a photocopy marathon.
View industry FinanceFNOL packs, medical bills, and policy PDFs land as structured claims data with a human step on low confidence.
View industry FinanceApplications, bank statements, and KYC images extract into the underwriting file—missing pages are flagged, not guessed.
View industry More industriesContracts, intake forms, and evidence PDFs become searchable fields in the matter file instead of a shared drive dump.
View industryWhy it matters
Next Gen System treats data extraction as a production system—scoped outcomes, owned integrations, and measurable quality from day one.
Accuracy beats vanity automation. We define fields, build golden sets, and keep humans in the loop wherever thresholds demand it.
In practice, teams use this engagement to faster document processing, field-level confidence and review, integration into downstream systems, and measurable accuracy over time.
Most stalled programs share the same friction: unclear ownership after a pilot, and brittle scripts without monitoring. Later, no evaluation of quality or roi, and integrations treated as an afterthought tends to show up if ownership is unclear.
Outcomes & deliverables
Concrete results and artifacts—so stakeholders know what “done” looks like before build starts.
Business outcomes
You receive
How we structure the work
Each workstream is a chapter of delivery—not a checklist item. Together they move you from scoped intent to owned production.
Text and structure from messy documents.
Rules + models for target schema.
Human correction for low-confidence fields.
Retrain / retune from corrections.
Business impact
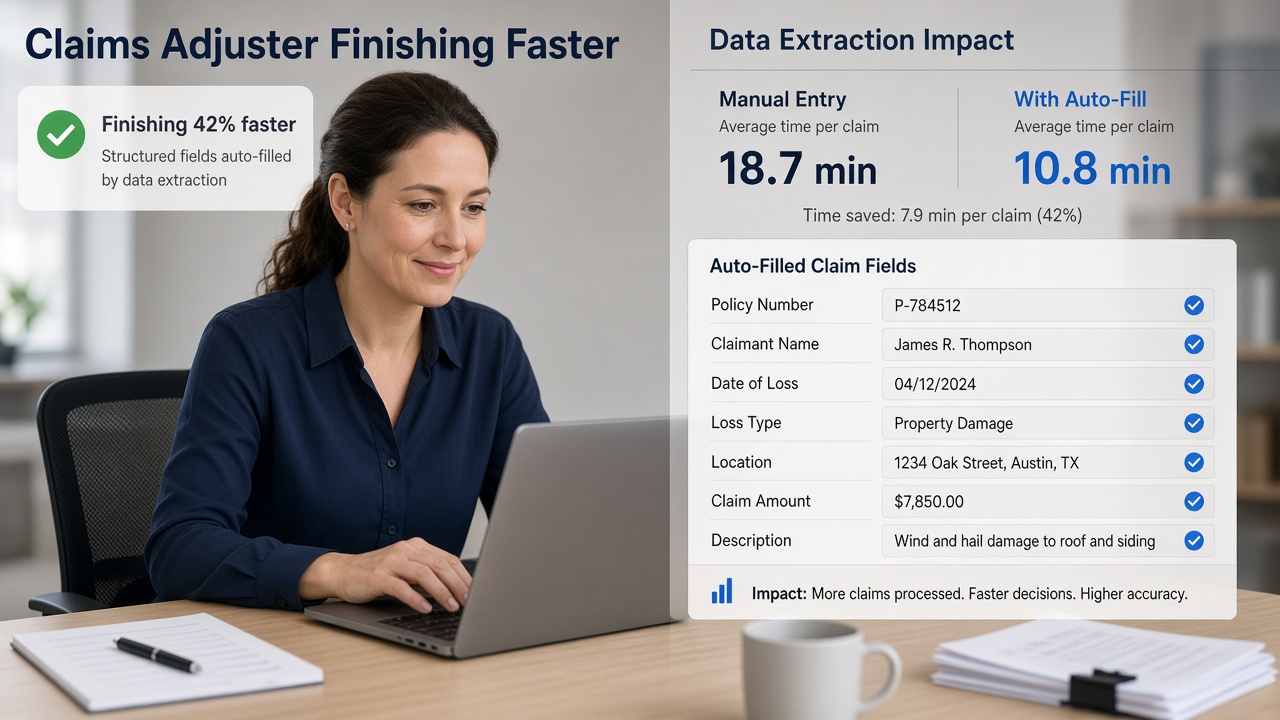
Faster document turnaround. Field-level confidence. Downstream system updates. Tracked accuracy over time.
You leave with extraction schema and golden set, production extraction pipeline, review ui / queue hooks, and accuracy reports and retraining loop—assets your operators can run without another consulting cycle.
Typical stack choices include OCR, Layout / LLM extract, Queues, and ERP / CRM hooks—selected for your compliance, latency, and ownership needs rather than a fixed tool wishlist.
We scope the win, build with evals, and hand over a system your team can run.
We map high-ROI chatbot, voice, automation, or data use cases—then pick the first win that can reach production.

We design the system, integrate your stack, and prove quality with evals before wider rollout.
We ship with monitoring, feedback loops, and a clear runbook so your team can own the system.
Good fit
Not a fit
FAQ
Straight answers for evaluating Data Extraction with Next Gen System.
We assess quality on your samples; some docs need heavier review by design instead of fake 99% claims.
We set field-level confidence thresholds on a golden set and route low-confidence fields to humans.
Yes. Integrations push structured fields into ERP, CRM, or claims systems after validation.
PDFs, emails, forms, and common image scans. We expand after proving the first schema.
Yes—review queues feed a feedback loop so accuracy climbs on your real document mix.
Depends on volume and review rate. We design for your turnaround SLA, not a demo average.
Related
Share your use case. We respond within one business day.