Next Gen System builds production chatbots, Voice AI, bot & process automation, agentic systems, OpenAI integrations, and data services—wired to your workflows.
Next Gen System builds production chatbots, Voice AI, bot & process automation, agentic systems, OpenAI integrations, and data services—wired to your workflows.
Service
Assistants, RAG, PDF analysis, search, and generative media—measured, not prompt-only.
Built for Product and ops teams that need LLM features beyond a single vendor API demo.
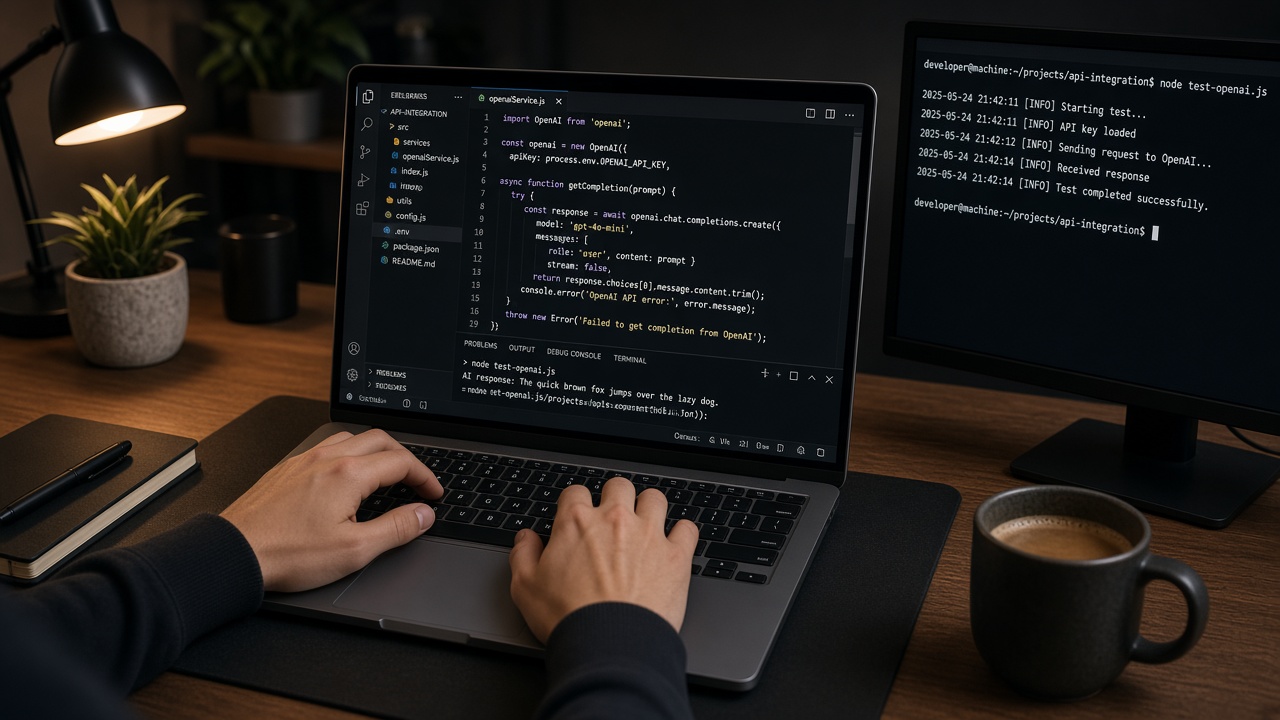
Next Gen System builds production LLM applications: custom assistants, document and PDF analyzers, RAG knowledge bases, AI search, recommendations, and image/audio/video generation—wired to your data, auth, and cost controls.
Assistants, RAG, search, PDF analysis, and generative apps on OpenAI, Claude, and Gemini.
Project types
Concrete builds we ship under this service—not a generic AI wishlist.
Industries
How this service shows up in each sector—specific jobs, not a generic industry list.
Assistants and document analyzers sit on your policies and EHR extracts with RAG and citations. Clinical decisions stay with licensed staff.
View industry FinanceClaim and policy assistants read packs with citations. Adjusters get a draft; the system records what the model used.
View industry FinanceResearch copilots, RAG over filings, and summarization tools answer from your corpus—not a public chat window with no provenance.
View industry More industriesProposal, research, and knowledge assistants pull from your matter files with evals so a hallucinated clause does not ship.
View industryWhy it matters
Next Gen System treats generative ai / llm as a production system—scoped outcomes, owned integrations, and measurable quality from day one.
A ChatGPT wrapper is not a product. We design LLM systems around your documents, tools, and users: retrieval, analyzers, search, recommendations, and multimodal generation with evals and cost control.
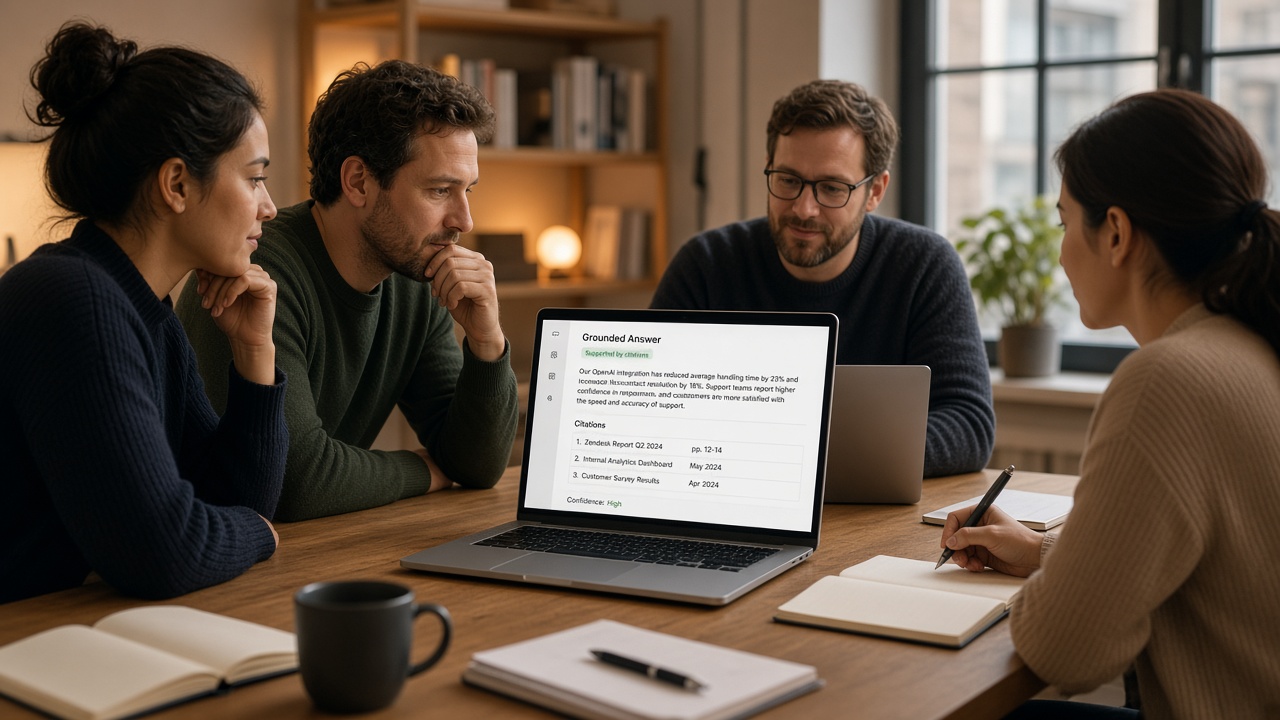
In practice, teams use this engagement to model choice by task: openai, claude, gemini, or llama, grounded answers with rag and citations, document, search, and content workflows in production, and prompt versioning, evals, and spend visibility.
Most stalled programs share the same friction: unclear ownership after a pilot, and brittle scripts without monitoring. Later, no evaluation of quality or roi, and integrations treated as an afterthought tends to show up if ownership is unclear.
Outcomes & deliverables
Concrete results and artifacts—so stakeholders know what “done” looks like before build starts.
Business outcomes
You receive
How we structure the work
Each workstream is a chapter of delivery—not a checklist item. Together they move you from scoped intent to owned production.
Custom copilots with tools and memory bounds.
Indexes, citations, and evals on real questions.
PDF, email, and unstructured document pipelines.
Text, image, audio, or video where it earns ROI.
Business impact
Grounded assistants on your knowledge. Faster document and research cycles. Search and ranking users actually trust. Visible quality, latency, and spend.
You leave with llm architecture and threat model, production assistant / rag / analyzer, eval suite and prompt versioning, and usage, quality, and cost dashboards—assets your operators can run without another consulting cycle.
Typical stack choices include OpenAI / Claude / Gemini / Llama, RAG / vectors, Evals, Your APIs, and Observability—selected for your compliance, latency, and ownership needs rather than a fixed tool wishlist.
We scope the win, build with evals, and hand over a system your team can run.
We map high-ROI chatbot, voice, automation, or data use cases—then pick the first win that can reach production.

We design the system, integrate your stack, and prove quality with evals before wider rollout.
We ship with monitoring, feedback loops, and a clear runbook so your team can own the system.
Good fit
Not a fit
FAQ
Straight answers for evaluating Generative AI / LLM with Next Gen System.
Whichever fits the job: OpenAI, Claude, Gemini, Llama, or a mix with routing and fallbacks.
Yes. RAG with evals so answers stay cited—or we flag low-confidence instead of hallucinating.
Where there is a production use case. We do not bolt generators on for the pitch deck.
OpenAI Integration is wiring GPT into your stack. This service is the full LLM product: RAG, analyzers, search, and multi-model apps.
Related
Share your use case. We respond within one business day.